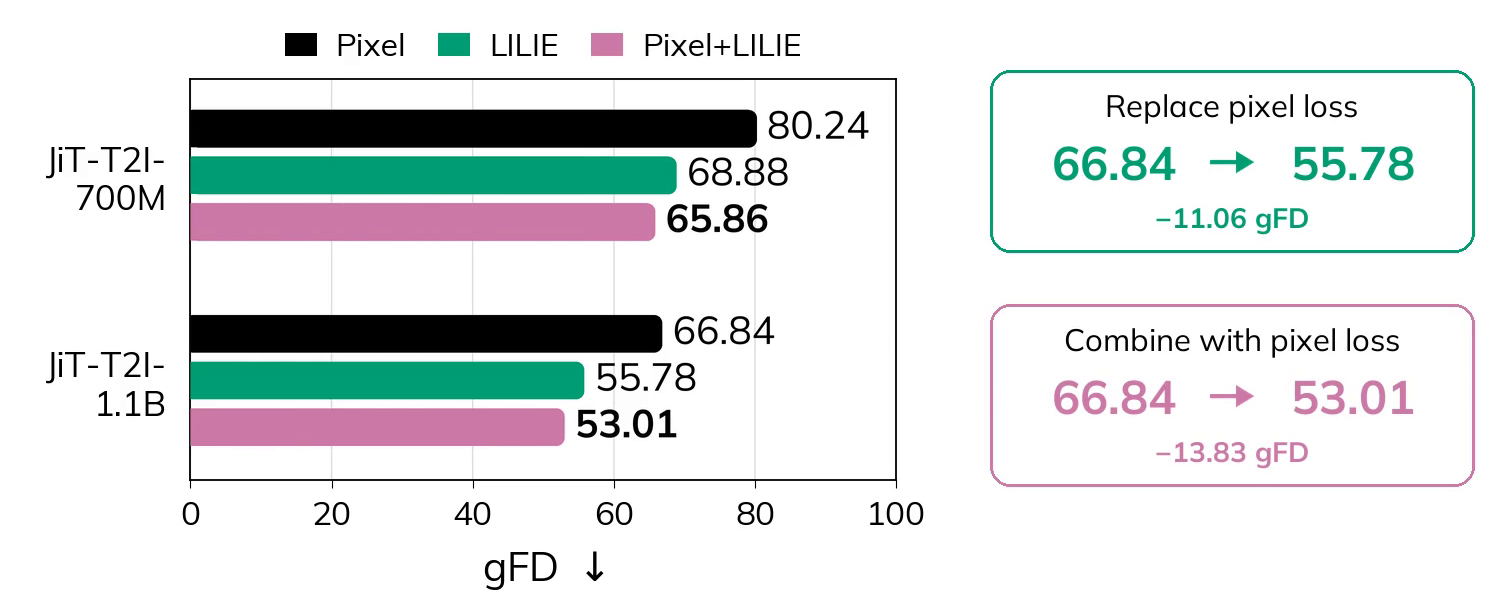
End-to-end visual generation with pixel-space loss has recently achieved competitive performance without the need for learned image tokenizers. In this work, we study whether language-informed supervision can provide a richer training signal than pixel loss for visual generation. We introduce LILIE (pronounced “lily”), a Language-Informed and Lossless Image Encoder. LILIE is an invertible image transform trained such that a vision-language model can recover captions from noised features. The encoder uses a normalizing flow transformer trained jointly with a vision-language model via next token prediction. We then use the encoder to extract a simple language-informed loss for text-to-image generation. We train JiT models with LILIE loss, reducing gFD by 14 points (66.84 → 53.01) against a pixel-only baseline on the GPIC dataset.
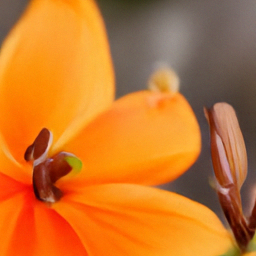
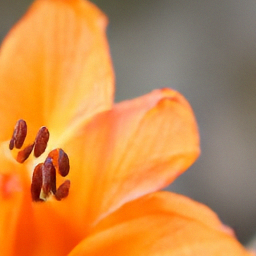
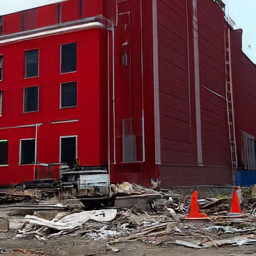
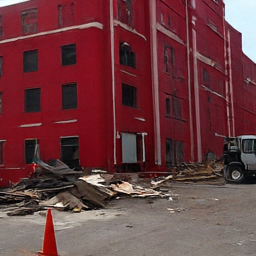
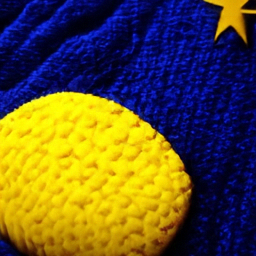
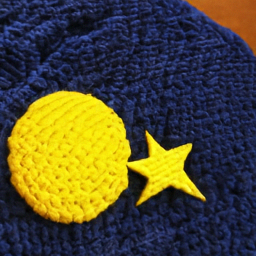
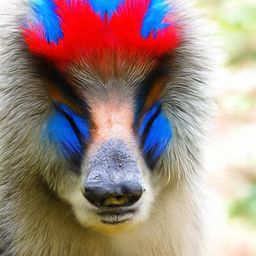
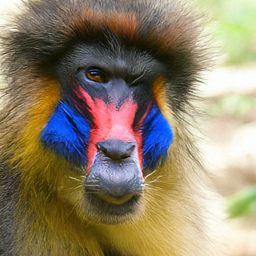
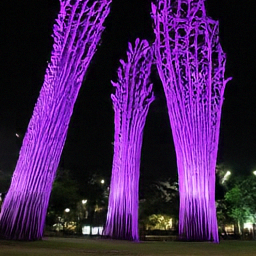
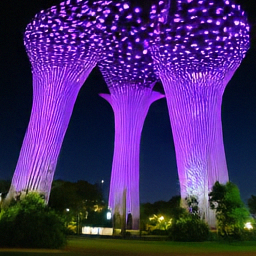
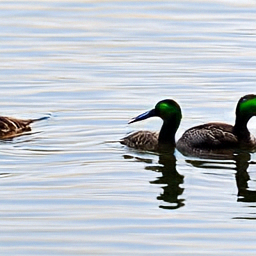
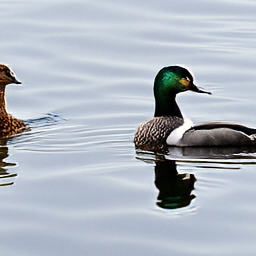
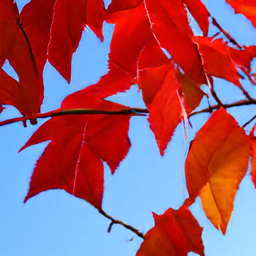
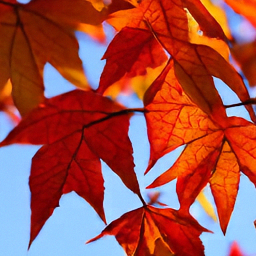
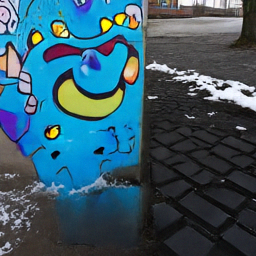
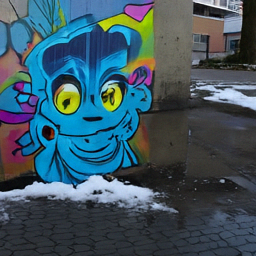
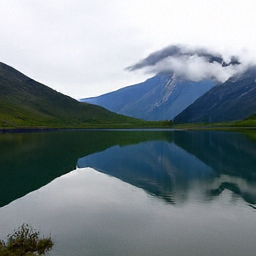
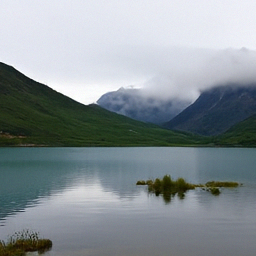
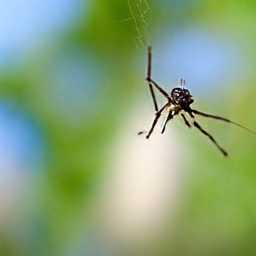
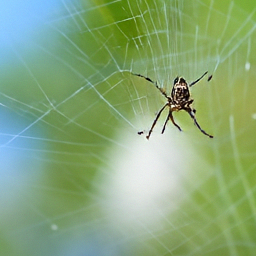
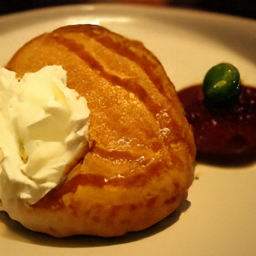
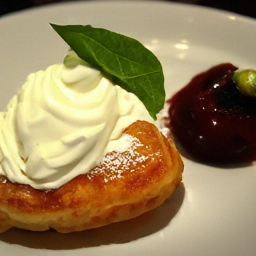
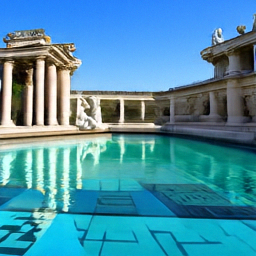
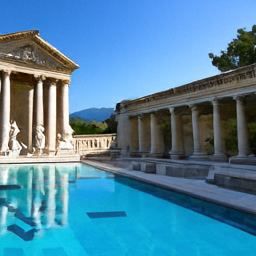
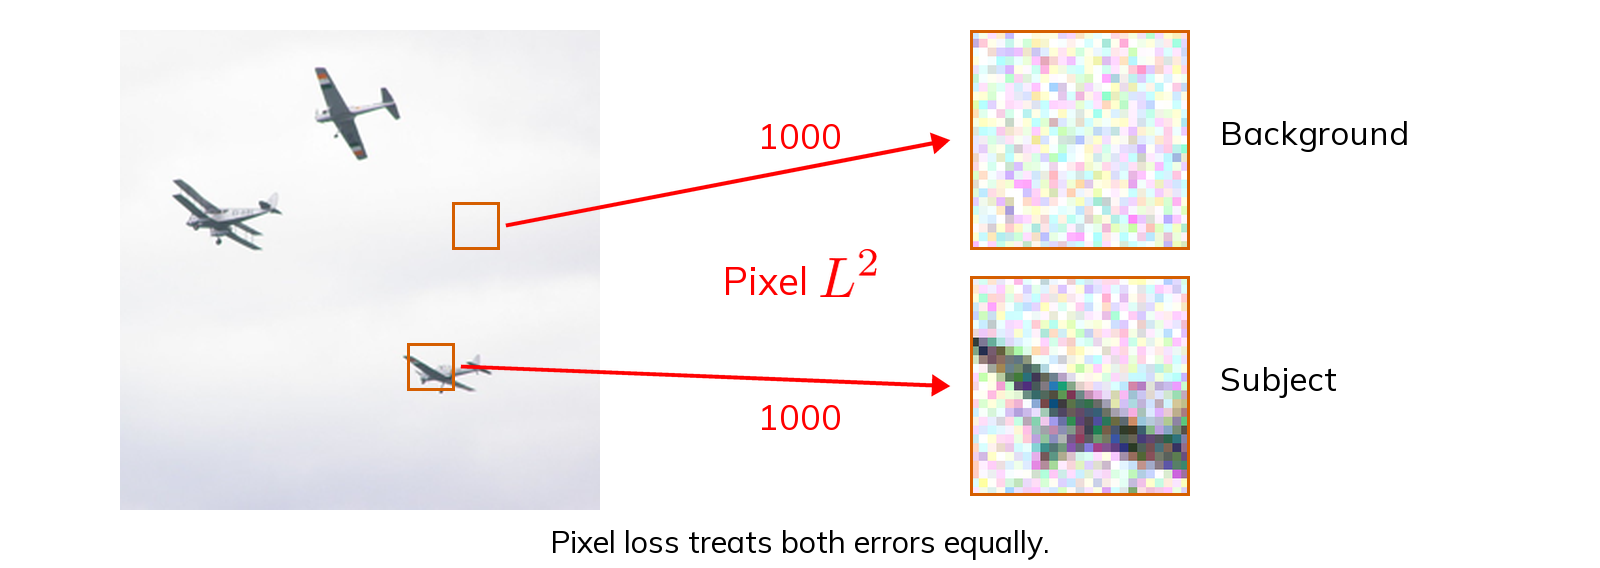
Pixel loss treats every pixel equally, but pixels contribute unevenly to image semantics. The above example shows two errors of equal pixel distance. One alters background texture while the other degrades a subject, yet pixel loss treats them the same. We hypothesize that language may help address this gap. In this work, we learn a visual space from image-caption pairs (GPIC) with an invertible image transform.
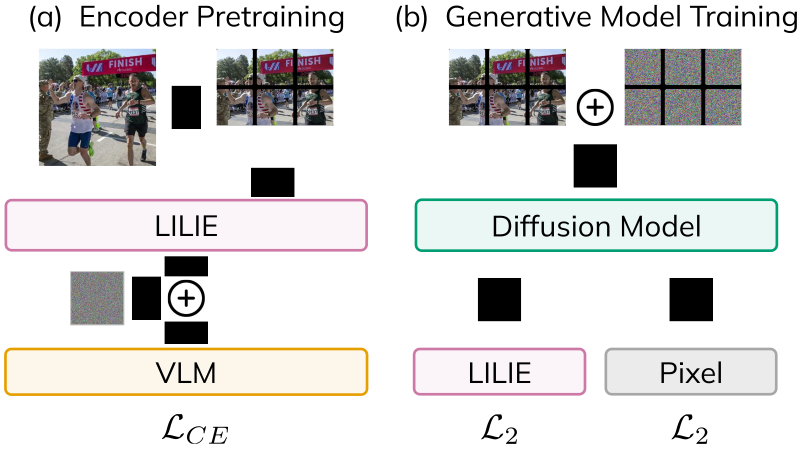
LILIE is an invertible encoder built with the TARFlow architecture. We train the encoder by passing an image through the encoder, corrupting the encoded image with additive Gaussian noise, then captioning the noised features with a LoRA-finetuned VLM. The objective is a standard cross-entropy loss against ground-truth captions from the GPIC corpus.
Once we have LILIE, we use L2 distance in LILIE space to supervise JiT training. LILIE loss works on its own and improves generation quality over a pixel-only baseline (66.84 → 55.78 gFD), and combining LILIE loss with pixel loss further improves gFD to 53.01.
LILIE loss alone improves gFD at both the 700M and 1.1B JiT-T2I sizes, and combining Pixel+LILIE loss improves gFD further. Models are trained for 390,600 steps (one epoch) on GPIC.
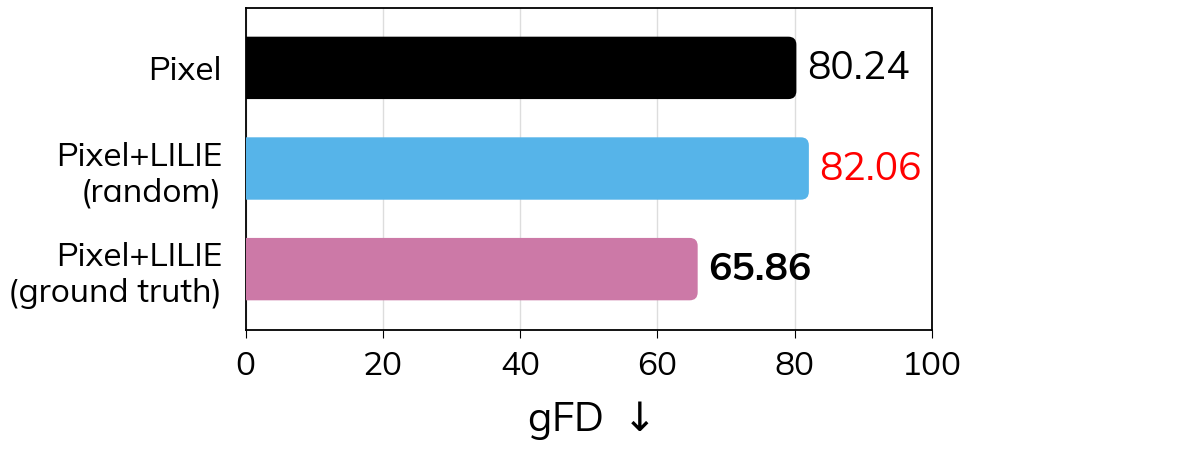
We train a LILIE encoder by replacing captions from GPIC with random tokens. For JiT-T2I-700M, the resulting gFD worsens over the Pixel baseline, indicating that informative captions play a crucial role during LILIE training.
Click a pair to zoom in.


@misc{agarwal2026lilie,
title={A Language-Informed Loss for Visual Generation},
author={Suchir Agarwal and Keshigeyan Chandrasegaran and Ziyu Chen and Kyle Sargent and Juan Carlos Niebles and Li Fei-Fei and Jiajun Wu},
year={2026},
eprint={2610.23653},
archivePrefix={arXiv},
primaryClass={cs.CV},
url={https://arxiv.org/abs/2610.23653},
}